
Attach the PDF to an AI assistant and ask for a script written for listening, at a set length: about 150 words make a spoken minute. Check every name, number and "must" against the page, then voice it. But scripts can run shorter than you asked, and some tools cannot read a scanned page at all.
We make Kukarella, so keep that in mind. Where another tool, a human voice or your own recording is the better choice, this article says so.
In January 1976, Ray Kurzweil's company announced a machine that read printed pages aloud to blind people. Walter Cronkite read his own sign-off with it on the evening news of 13 January 1976. Soon after, Kurzweil recalls, the only working machine died a couple of hours before a live appearance on the Today show. The chief engineer took it apart and put it back together, and it still would not run, so he slammed it against a table, and it worked. Stevie Wonder heard about the show and left in a taxi with the first production unit.
That machine said the printed words, in order. The Library of Congress began buying talking books for blind readers in 1934, and by 1995 its guide listed among a narrator's duties "writing accurate, concise descriptions for illustrations, graphs, charts, and tables". A page holds more than words, and a chart cannot simply be read aloud: someone has to decide what it says. That decision is the step between a PDF and a script, and an AI can now make it for you, if it sees the chart at all, or make it wrongly without a word.
 A library of documents nobody has heard yet.
What is a script, and how is it different from a summary or a read-aloud?
A script is your document rewritten to be heard once, in order, in short spoken sentences, with every point kept. But ask an AI for "a script" without saying more, and it may hand you a summary.
A PDF is written for the eye. A listener hears each sentence once, at the speaker's pace. So "turn my PDF into audio" can mean four things:
| Kind | What you get | Use it for |
| Read-aloud | Every word in printed order, page numbers and footnotes included | An approved text whose wording is the rule |
| Script for the ear | Every point in order, in short sentences; figures described | A lesson, a chapter, a procedure |
| Summary | The main points only; detail and exceptions dropped | A recap, never a policy |
| Dialogue | The content shared between two or more speakers | A role-play, a question-and-answer |
If you get a summary instead, say so in the request: "Do not summarise. Keep every point and every number, in the document's order. Rewrite only so it can be heard." And ask for a length that can hold the section: two minutes cannot carry ten pages (see "How long will the script and the audio be?" below).
 Ask about the whole document, not only for a summary.
How do I turn a PDF into a script, step by step?
Ask for a script with a stated audience and length, check it against the page, then voice it. But the middle step is yours, and no tool does it for you.
- Ask. Attach the PDF and write four things: who will listen, how many minutes, which section, and what must stay exact. For example: "Turn section 2 of the attached chapter into a five-minute narration for Year 9 history students. Keep every date and name."
- Check. Read the script beside the page, with the checklist under "How do I check a script line by line?" below.
- Voice. Choose a native voice of the variety your learners will hear. Listen once to the end, download the audio, and keep the script as its transcript.
In Kukarella, use "Create Voiceover" on the home page or "Use Assistant" inside Text to Voice for one narrator, and "Create Dialogue" on the home page or "Use Assistant" inside DialoguesAI for two or more speakers. Click "Upload files" ("Attach file" on the home page), add the PDF and type your request.
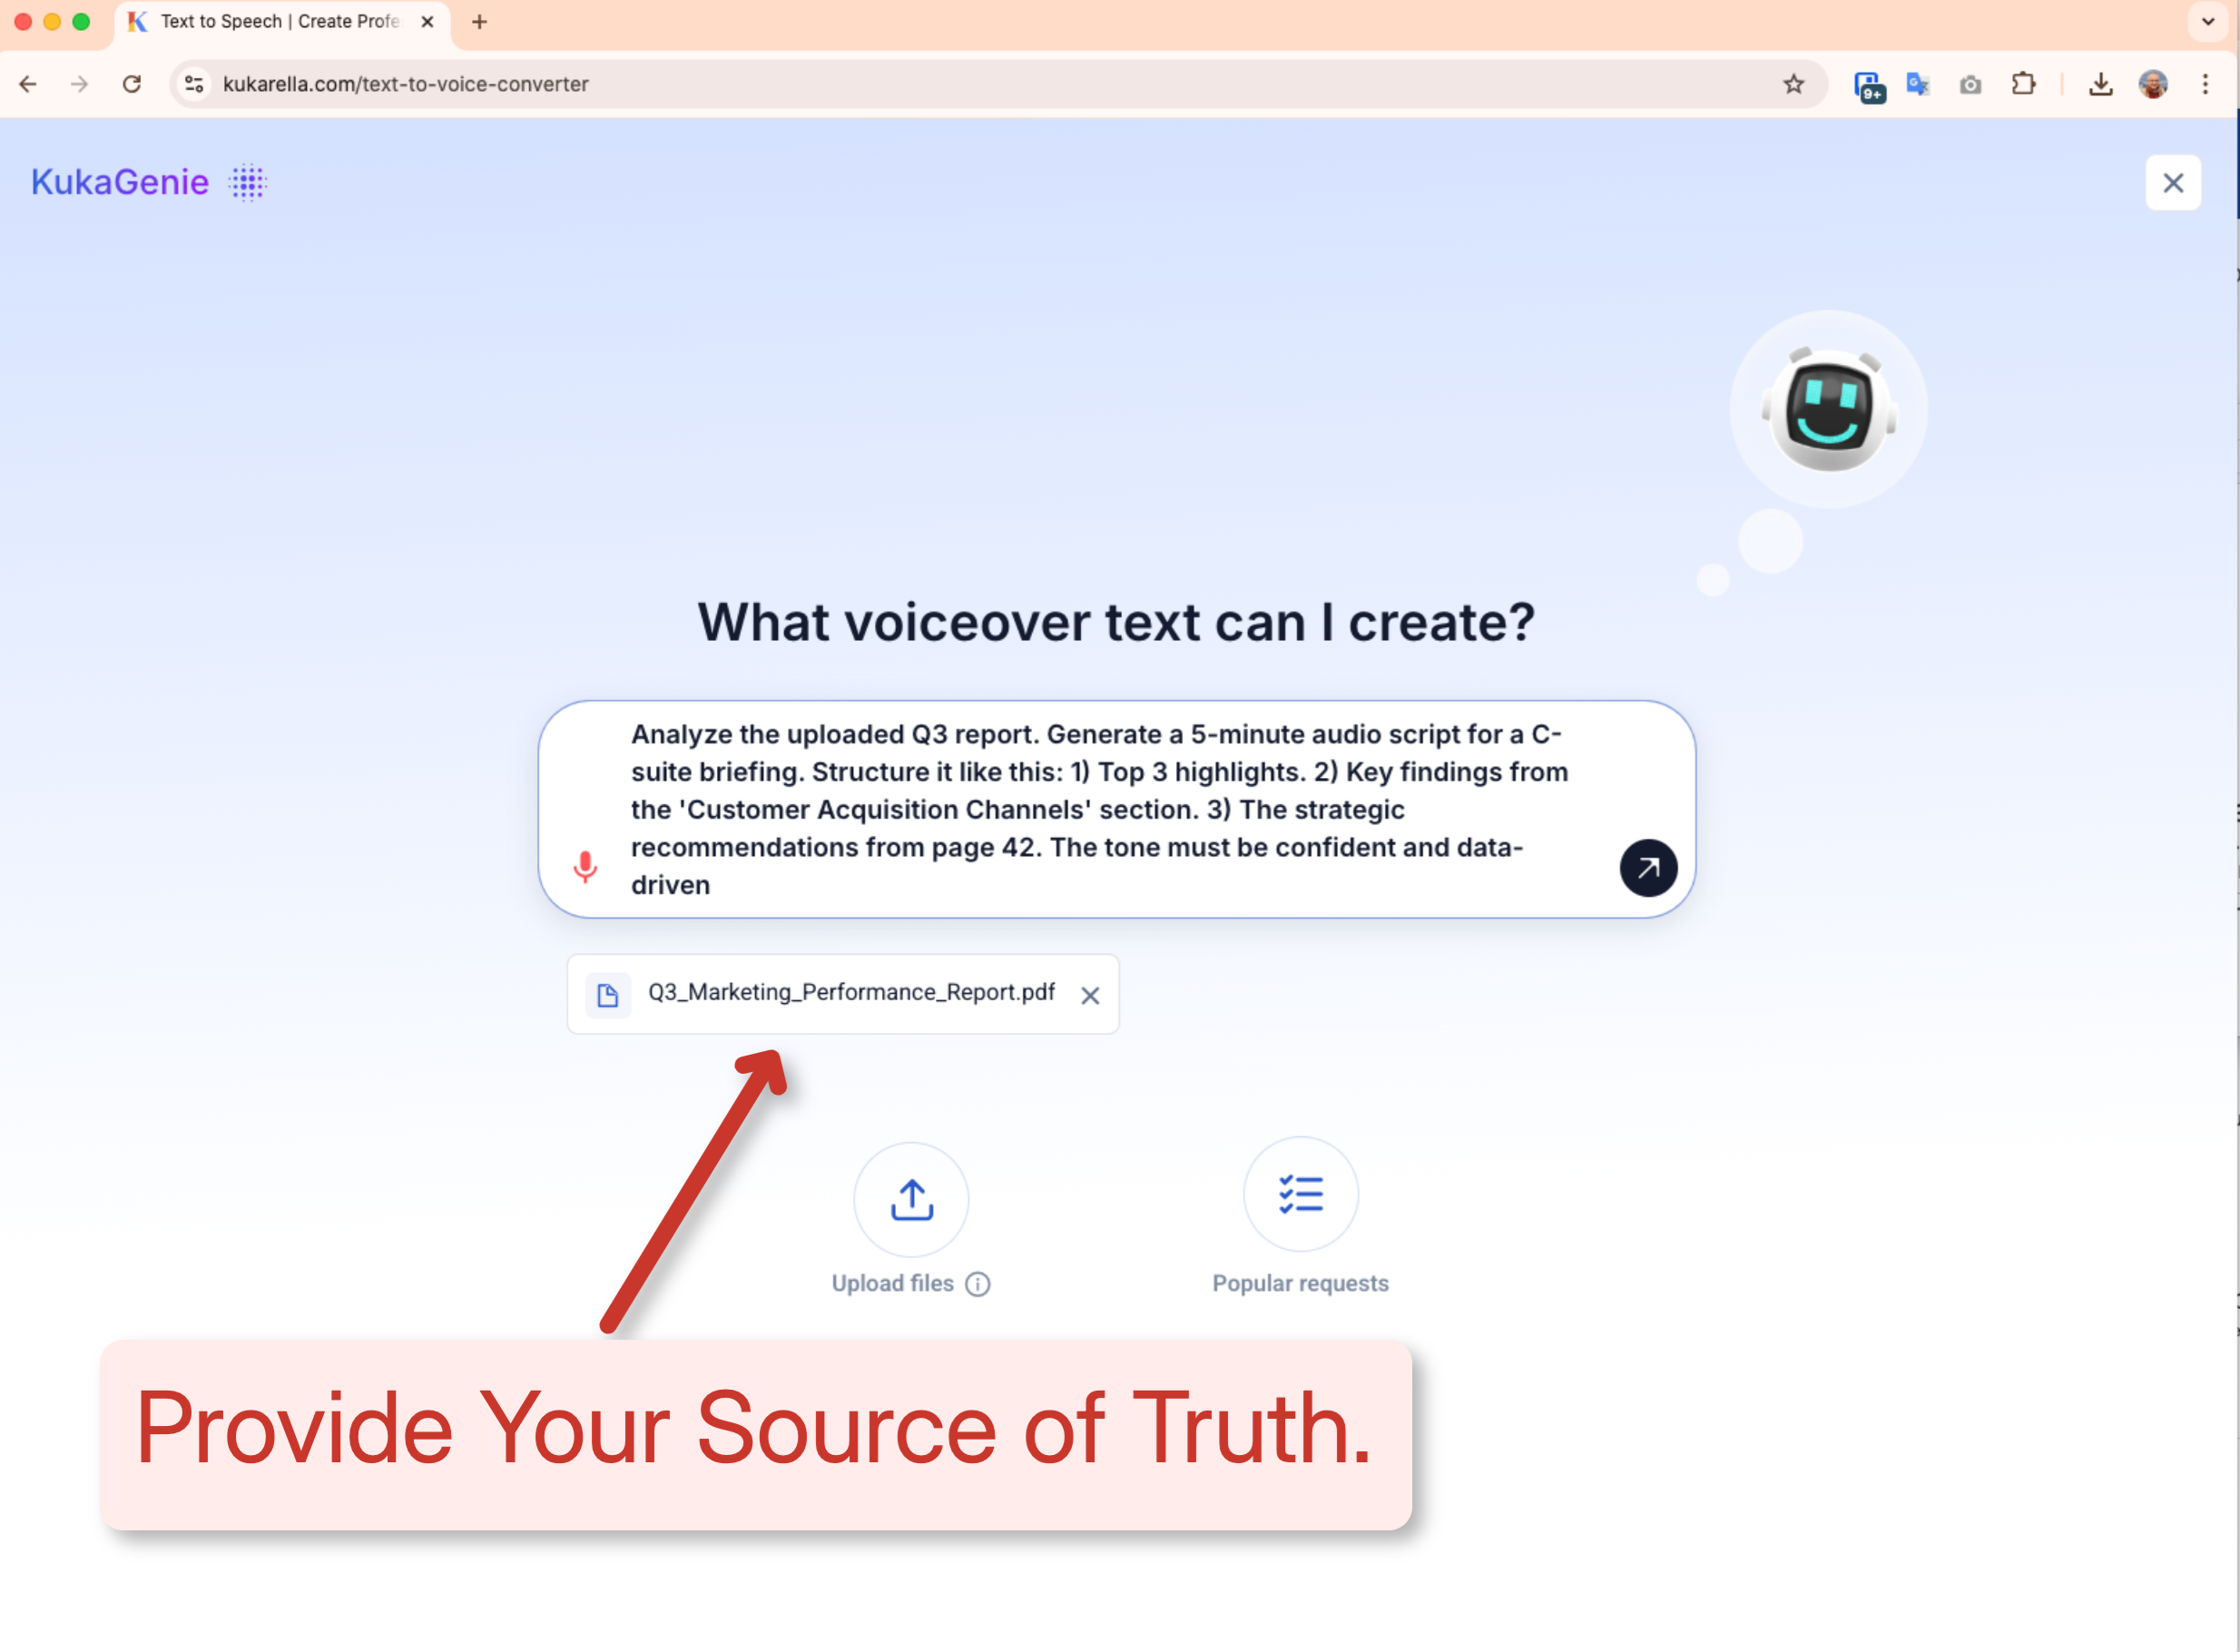 Attach the PDF, then say who will hear it, how long it should run and what must stay exact.
The assistant takes up to 10 files of PDF, DOCX, TXT, JPG or PNG, 20 MB each, as the tooltip beside "Attach file" says, but not PowerPoint or old .doc files.
 The assistant takes PDF, DOCX, TXT, JPG and PNG, up to 10 files of 20 MB each.
Ready-made requests sit under "Popular requests", as our 2025 screen recording shows, in the interface of that time:
Writing the script costs no credits: our product code, read on 3 October 2026, charges nothing for it, and gives a guest 3 requests and a free account 10 in each assistant; paid plans have no limit. But voicing costs 1 credit a character with a ready-made voice, spaces included, charged when you press Play.
Can AI read a scanned PDF?
If you can select a PDF's words with your mouse, an AI tool reads them exactly. But a scanned page is only a picture of text, and tools differ on whether they read it at all.
The test is one drag of the mouse. Open the PDF and drag across a word; in our sample policy below, try "Vargas-Okafor". If it highlights and copies, the PDF carries a text layer, as files exported from Word or Google Docs do. A scan saved without text recognition holds only pictures of pages. Some scanning apps add the layer for you: Adobe Scan does it by default, but its free version skips text recognition on scans longer than 5 pages on Android (25 on iPhone). The picture below sums it up.
 Drag over a word: if it highlights, the words are read exactly; if not, the page is read as a picture.
In Kukarella, a scanned page is read as a picture. Pages with a text layer are read from it, in your browser. A page without one is sent to an AI vision model, run by another company, which copies its text word for word, a table row by row. Up to 20 scanned pages of one PDF are read, at no charge, and any after that are named in a message, so you can upload them as a second file. A PDF with no readable text at all is not attached, and a message says so. In our test on 3 October 2026, a two-page scan with no text layer came back as a script that named Dr. Imelda Vargas-Okafor and extension 4417. But the model skips any word it cannot read with certainty, and nothing marks the gap, so check every name and number against the page.
Other tools differ on scans, and some do not say. Claude analyses the images as well as the text in PDFs of up to 100 pages, and only the text in longer ones. Wondercraft says it does not support scanned image PDFs. The Speechify reader lists "Scan & Listen" as a Premium feature, but it is for personal use only. Test one page with a name and a number on it before you upload a whole scan.
For a long scan, or a tool that does not read pictures, there are two fixes:
- Add the text layer. Run text recognition in your scanning app, save the PDF again and repeat the drag test. The words are then read as printed, and Kukarella's 20-page limit no longer applies.
- Split the file. Upload the pages after the 20th as a second PDF.
Pages saved as JPG or PNG are read by the same vision model, but differently: a page of plain text is copied word for word, and a page with a figure is summarised into its key points.
Either way, the rest is the same: get the text, rewrite it for the ear, listen.
 Scan the page, get the text, rewrite it for the ear, listen.
What happens to tables, charts and footnotes?
When Kukarella reads a PDF's text layer, only its words arrive, so tables lose their columns and charts saved as pictures are lost. But one sentence of yours can carry what each chart shows.
Inside a PDF with a text layer:
- Pictures, and charts saved as pictures, do not come through. Other charts arrive as stray labels and numbers.
- Tables arrive as words and numbers, without the columns.
- Headers, footers, page numbers and footnotes come in as ordinary text. In our sample, the college's name at the top of each page arrives twice. The AI writer may drop such lines; nothing guarantees it.
A scanned page goes to the vision model instead: it copies the page's text, captions and table cells included, and does not describe the pictures.
Joel Gladd, voicing his own textbook in April 2026, replaced each table with a short spoken note and skipped the figure captions. Before you upload:
- Write the point of each chart into the text, in one sentence: "Most spills happen in the last ten minutes of a class."
- Keep the one comparison that matters from a table, and leave the table in the handout.
- Say what to look at when the visual stays in front of learners: "On the handout, follow the red line. It rises after March." When reading the chart is the lesson, talk over the slide yourself.
- Or upload the chart as a picture. The vision model describes it and quotes its labels. But it is not asked to read off every value, and it does not see your request.
The picture route, on a diagram:
 A carbon-cycle diagram uploaded as a picture, with the request typed above it.
And the script that came back, in 2025, from an earlier version of our instructions; today's scripts no longer open with a title or use brackets. Every stage it names still needs a check against the diagram.
 The script that came back, written for 9th graders.
Should the AI keep my words or rewrite them?
Keep the exact words when the wording is the rule, and have them rewritten for the ear when understanding matters more. But never let an AI rewrite a text you will be held to without checking every line.
One question sorts most pages: if a learner remembered only the gist, would that be enough? If not, the wording is the rule, as in most policies, procedures and exam texts. The Library of Congress's narration specification of 2025 still requires its narration to "conform to the source material text… in its entirety".
But a page read aloud as it stands is hard to follow. In a 2011 study, pupils learning to read a temperature graph did worse when the explanation was narrated beside the graph than when the same text was printed beside it; in a second experiment, with other pupils and both texts shortened, the narration no longer lost (Leahy and Sweller). Across 46 studies, listening and reading came out about even, but reading came out slightly ahead (g = 0.13) when readers set their own pace (Clinton-Lisell, 2022). A listener hears each sentence at the voice's pace and cannot glance back, so the script must carry the pace: short sentences, one idea each, signposts. An AI draft saves you the rewriting, not the reading.
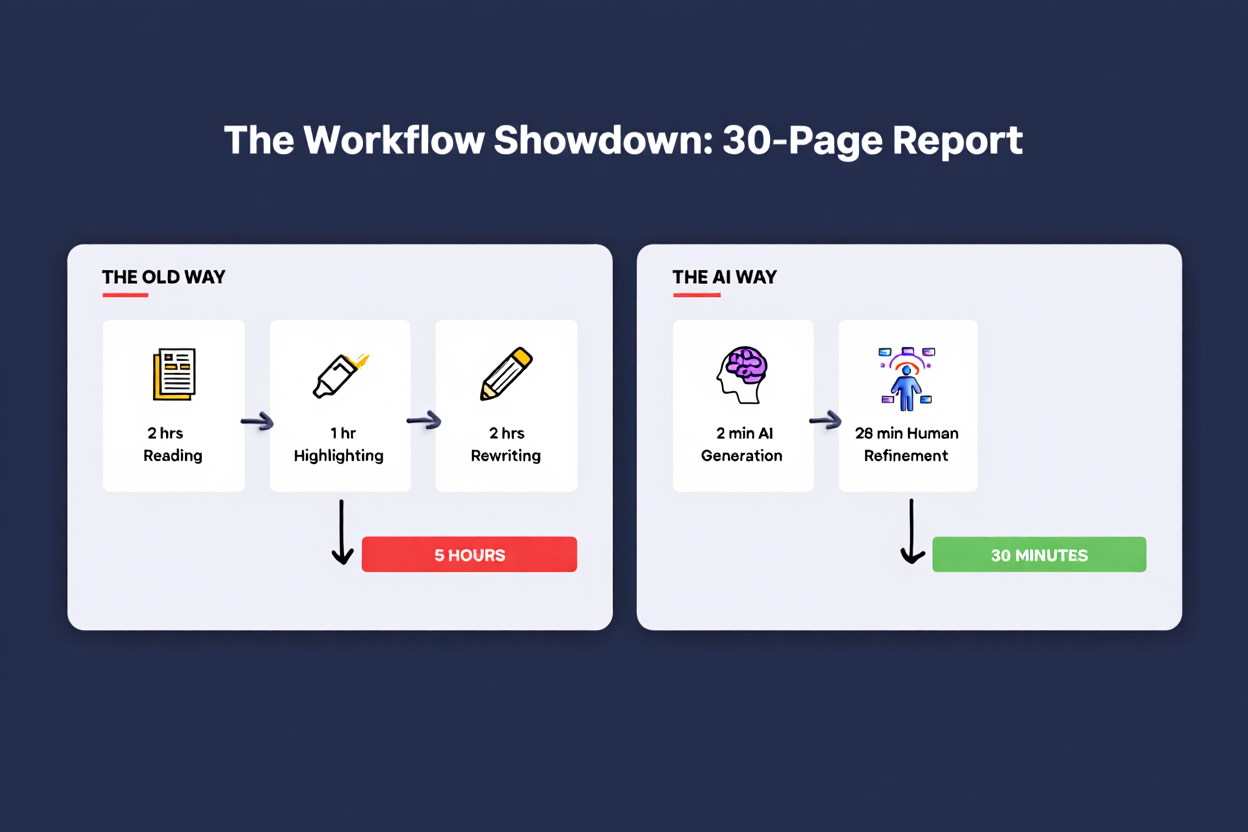 Reading, highlighting and rewriting by hand, against an AI draft and a human edit.
In Kukarella there is a route for each.
- Word for word. In Text to Voice, the "Media" icon puts the document's own words into the editor without rewriting them; or paste the approved text into a blank project. Skip the assistant here: it always writes a new script. "Ask AI" edits text already in a project and takes no file.
- Rewritten for the ear. The assistant writes a new script, aiming at the length you ask for; it often comes back shorter, as the next section shows.
How long will the script and the audio be?
About 150 words make one minute of narration, so a five-minute script is about 750 words. But in our tests the script came back shorter than asked, with no warning.
The figure is the National Center for Voice and Speech's average for American English, close to ACX's 2013 estimate of 9,300 words per finished hour of audiobook, or 155 a minute. In April 2026 Joel Gladd's longest chapter, about 6,400 words, made 42 minutes 49 seconds of audio for $1.34 through Gemini Pro. Our assistant is told the same: "Five minutes is about 750 words." If the voice reads slower, at 130 words a minute, the same script runs about 15% longer.
| Minutes of audio | Words to ask for | Characters, about (= credits with a ready-made voice) |
| 1 | 150 | 900 |
| 2 | 300 | 1,800 |
| 5 | 750 | 4,500 |
| 10 | 1,500 | 9,000 |
Kukarella has no length setting; you ask in minutes or words, in the request. Its instructions say "Coming in at half the length asked for is a failure, not a safe choice." Still, in our tests in August 2026, a request for a 10,000-word script came back at about 2,300 words, and a 19-page upload became a script of about 3,500 characters, about four minutes of speech. On 2 October 2026, a request for a two-minute dialogue came back at about 700 characters, which plays in under a minute. None came with a warning; each is a single run.
So ask for one section per request, count the words that come back, and send any missing part on its own. Start with a section you know well, so you notice what is missing.
 Start with one section you know well: a lesson, a chapter, a policy.
At about 6 characters a word, spaces included, ten minutes is about 9,000 credits with a ready-made voice: 3% of the 300,000 a month that Prime includes for $21 (Pricing page, 3 October 2026). The estimator does the sum for your own section, either way round:
What happens to one policy page, word for word and rewritten?
In our run, the assistant kept every rule of the sample policy when the request named the words to keep. But a plain request for a one-minute voiceover came back with sentences the policy never says.
The page is a sample we wrote for this test, with an invented college and invented people: if their names and numbers appear in a script, the file was read. The PDF has a text layer, and both pages open with the same header:
Page 1
Harbourview College - Lab Safety Policy
Section 4. Eye protection
Safety glasses must be worn at all times in Room B-214, including during clean-up. Visitors receive a pair at the door. The lab supervisor, Dr. Imelda Vargas-Okafor, checks the eyewash station every Monday. Report a missing pair to extension 4417.
Page 2
Harbourview College - Lab Safety Policy
Section 5. Spills
Report every chemical spill within 15 minutes, even a small one. Use the yellow kit under bench 7. Never wipe an unknown liquid with paper towels. The spill log is kept by the technician, Mr. Tobias Lindqvist, in the blue folder by the door.
Route 1: word for word. Through the "Media" icon, the text lands in the editor without rewriting, as one paragraph: the header twice, and the lines broken where the PDF's printed lines end.
 The policy as it lands through the Media icon: one paragraph, the header twice, lines broken as printed.
Delete both headers. What is left, section headings included, is 91 words and about 533 characters: about 36 seconds at 150 words a minute, and about 533 credits with a ready-made voice. Listen for "B-214", "Dr.", "bench 7" and "4417": a voice may read the extension as a number in the thousands, and staff need four digits. With a native English voice:
The policy word for word, voiced by Aria
Route 2: rewritten. We attached the same PDF to "Create Voiceover" on the home page with this request:
Turn the attached policy into a two-minute narration for new lab staff. Keep every "must" and "never" exactly as written.
Name your own document's rule words the same way; yours may say "shall" or "only". Two minutes is about 300 words, more than three times the 91 on the page, so the assistant had to add words or come back short. The script it returned, unedited:
For eye protection, safety glasses must be worn at all times in Room B-214, including during clean-up. Visitors receive a pair at the door. The lab supervisor, Dr. Imelda Vargas-Okafor, checks the eyewash station every Monday. Report a missing pair to extension 4417.
For spills, report every chemical spill within fifteen minutes, even a small one. Use the yellow kit under bench seven. Never wipe an unknown liquid with paper towels. The spill log is kept by the technician, Mr. Tobias Lindqvist, in the blue folder by the door.
Its length: 89 words and 530 characters, about 40 seconds: a third of the two minutes we asked for. It came back short rather than padded. It opened in the editor in paragraphs, with a voice already chosen:
 The returned script in the editor, in two paragraphs, with the voice the assistant chose.
We changed that voice to Aria, a native US English voice:
The rewritten script, voiced by Aria
The check, rule by rule. Anything the AI writes beyond the policy is its own writing, not the policy.
| In the policy | Why it must survive | In the script |
| "must be worn at all times" | The obligation and its reach | Kept |
| "including during clean-up" | The moment people forget | Kept |
| "within 15 minutes, even a small one" | A deadline, never rounded | Kept, as "fifteen minutes" |
| "Never wipe an unknown liquid with paper towels" | The one prohibition | Kept |
| Room B-214, bench 7, extension 4417 | Places and numbers staff act on | Kept; "bench seven" in words |
| Dr. Imelda Vargas-Okafor, Mr. Tobias Lindqvist | Who to go to | Kept, with their roles |
| Anything the policy does not say | Each added sentence is new policy | Only two openers: "For eye protection" and "For spills" |
Our writer is told to spell numbers and abbreviations out, so "15" may come back as "fifteen" and "Dr." as "Doctor": count those as kept when the spoken value is right.
What the example shows. New staff should hear the policy word for word: route 1 is the policy. Here the rewrite stayed so close to it that either recording would do. But that is one run, with a request that named the rule words.
The same policy, with a plainer request. The same day we attached the scanned copy of the policy to "Create Voiceover" and asked only: "Write a one-minute voiceover from the attached file." The script, 132 words, kept every name and number, spelling them out as "B two one four" and "four four one seven". It also:
- added two sentences of its own: "That routine matters because quick access to eye rinsing can make a real difference after an accident" and "In the lab, fast reporting and careful cleanup help protect everyone";
- added an instruction the policy never gives: "so make sure the incident is recorded";
- turned an order into a softer line: "any missing pair should be reported";
- dropped both roles, "the lab supervisor" and "the technician".
Each line is plausible, and none of it is in the policy. That is what the check is for.
What breaks when a page is read aloud?
Long sentences, brackets, "see Figure 3", acronyms and strings of figures fail in the ear, because a listener hears each sentence once. But each has a one-line fix, and every fix is a rewrite to check.
The fixes, from broadcasters and plain-language guides:
- One idea per sentence. GOV.UK says to "split up sentences that are over 25 words long"; the US Federal Plain Language Guidelines say: "Express only one idea in each sentence."
- Few numbers, rounded. The BBC News Styleguide of 2003, on radio, turns 1,497 workers into "fifteen hundred" (p. 51). But never round a deadline, a dose or an amount learners must act on.
- Acronyms in full the first time.
- No brackets, no "see Figure 3". Say what the figure shows.
- Signposts: "There are three steps. First…"
- Negatives in full. "Were" and "weren't" sound alike; say "were not" (BBC guide, p. 64).
- Rule words exactly. Keep every "must", "must not", "may" and "should" as the source has them. This rule is ours, for policies, not a broadcaster's.
Alison MacAdam of NPR Training put the craft in one line: "If you wouldn't say it that way, don't write it that way!"
Our assistant is told to do much of this already: sentences of 30 words at most, numbers and abbreviations in words, no brackets, headings or bullet lists, and each step in its own paragraph, because Kukarella splits the audio by paragraph. It is also told: "Do not add drama, debate or theatrical flourish the user did not ask for." Afterwards, only the script's language is checked, and stray pause tags are removed. Nothing checks sentence length, numbers or what the AI added.
"Ask AI" can make such fixes in place: choose "Replace original text" on its answer. Our 2025 recording shows where it opens, in the interface of that time. Its script carries stars, "Narrator:" labels and stage notes in brackets. A voice may read them aloud, so delete anything like them before you press Play.
Paste a page of your own below for its running time, the lines a listener may stumble on and the rule words to keep. Nothing you paste leaves your browser.
How do I check a script line by line?
Put the script beside the page and tick off every rule word, number, name and exception. But do not rely on the request, because asking an AI for accuracy does not make it accurate.
In a 2025 study, AI summaries of scientific papers stated findings more broadly than the papers did. Four model setups did so nearly five times as often as human summaries, and asking for accuracy made it about twice as likely (OR 1.90); the Claude models were among the exceptions (Peters and Chin-Yee). On Vectara's leaderboard of 22 September 2026, only 9 of the 108 models listed stay under a 5% hallucination rate when summarising a given passage. So your protection is the check, not a better prompt.
The checklist:
- Rule words. Every "must", "must not", "may", "should", "never" and "only" survives, word for word, and no order has turned into a "should".
- Exceptions and limits. Every "except", "unless", "even" and "including" survives, and "some" or "in this study" has not become "all".
- Numbers. Every deadline, dose, amount, date, room and phone number is exact: "within 15 minutes", not "quickly".
- Names and roles. Spelled as in the source, and the right person does the right thing.
- Added. Mark every sentence not in the page. One of our scripts told lab staff to "make sure the incident is recorded"; the policy never says so.
- Dropped. Tick each sentence of the page off against the script.
- Sound. Listen once to the end, with the page in front of you. Names, room numbers and extensions are where voices differ.
- Sign-off. For a policy, the person who owns it listens to the audio, not the prompt, before anyone else hears it.
In Kukarella, change one paragraph and only that one is voiced again. Type the change yourself, or use "Ask AI" in the project; unlike the assistant, it uses credits, about 1 for every 5 characters it sends.
 Ask AI, Edit project with AI, at the top of a Text to Voice project.
Which voice and accent should narrate it?
Choose a native voice of the variety your learners will hear, because Kukarella's assistant casts by gender and age, never by accent. But some varieties in our library have only two native voices.
The assistant picks from a fixed set of 22 voices by gender and age (our product code, 3 October 2026). So once the script opens, click the voice and pick a native voice of your learners' country from 2,000+ voices in 152 languages and accents. In Text to Voice, "Add voice" opens the Voice Library: type the language, then choose the country.
 The Voice Library open on English (US), with Aria, a native voice, selected.
French (Canada) had 56 native voice entries, and under Spanish (Argentina), 2 of the 67 voices listed were Argentine (our count of the Voice Library, 1 October 2026); a few entries are quality tiers of one voice. Two voices carry a dialogue, not a course with six Argentine speakers. Our guide to choosing an AI voice has the full method. Some voices also let you slow the pace: speed works on Microsoft voices, for example, and not on OpenAI's.
 On Microsoft voices such as Jenny you can pick a reading style and slow the speed.
Another language. Name it in your request, and the script comes back in it, whatever the PDF's language. Choose a native voice of that language, and have a speaker of it read the script first. There is no one-click "translate and re-voice".
A human voice. For young children who know your voice, or a story where the performance is the lesson, record it yourself or hire a narrator. In one 2024 study with adults online, a professional voice actor beat a synthetic voice on what listeners remembered and applied (Siegle and Craig). Earlier studies, the same paper notes, found a good synthetic voice did about as well as an ordinary recorded one.
Can I turn a PDF into a podcast or a role-play?
An AI can turn a PDF into a conversation between two or more speakers, as a podcast, a role-play or a question-and-answer. But every line a speaker says is a line the document never wrote, so this route needs the most checking.
Use it when learners should hear people doing something: a procedure acted out, or a conversation in the language they are learning.
What goes wrong. Two planetary scientists ran three papers, two of them their own, through Google's Audio Overviews, and every overview contained errors (Flynn and Peters, 2025). Google's own help page says Audio Overviews "may contain inaccuracies or audio glitches".
What our writer is told. Our instructions tell the AI writer not to add conflict you did not ask for: "Do not add drama, debate or controversy the user did not ask for." If you want a sceptical new employee asking practical questions, ask for one. Our 2025 demo shows a policy turned into a conversation between colleagues, in the interface of that time.
The check.
- Every fact a speaker states is in the document.
- The rule itself is said exactly once, or the word-for-word recording sits beside the role-play.
- The voices sound clearly different with your eyes closed.
- Nobody argues unless you asked them to.
In Kukarella, use "Create Dialogue" on the home page or "Use Assistant" in DialoguesAI. Each line is voiced separately, so you can change one line or one speaker; but a new voice for a speaker re-voices, and charges, every line of that speaker. One document can feed several scripts this way.
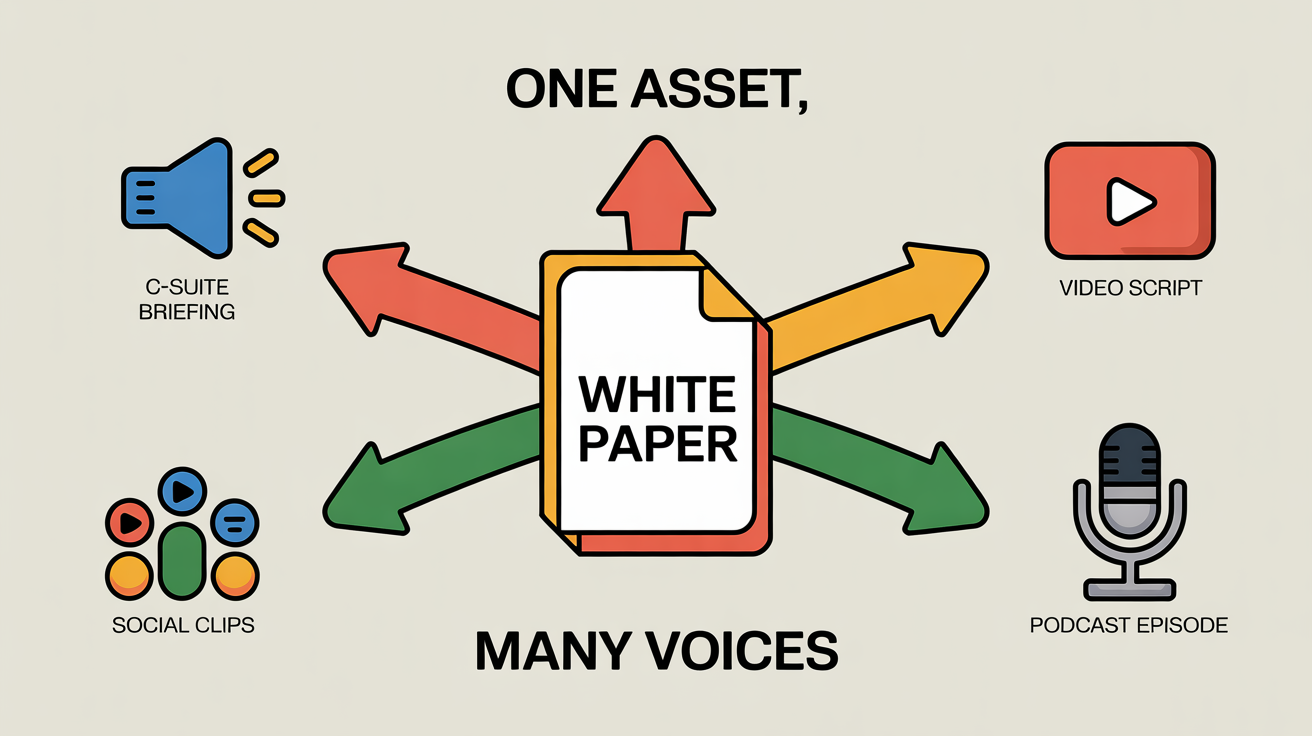 One document, several scripts: a briefing, a video, social clips, a podcast.
Which tool should I use to turn a PDF into narration?
Choose by whether you can read and fix the script before anyone hears it. But where a free plan gives you both a script and audio to download, ours included, that audio is for personal or non-commercial use only.
Gemini Notebook (NotebookLM until 16 July 2026) is free but goes straight to audio. ChatGPT and Claude give a script; for audio you need a second tool. ElevenLabs, Articulate 360 AI and Kukarella give both. Prices as read on 3 October 2026.
Gemini Notebook (called NotebookLM until July 2026)
- Script first: no; its help page offers no script to edit.
- Voices: no voice choice; 80+ languages, including Spanish (Mexico) and French (Canada), but English only once.
- Audio: a download, format not stated.
- Price: free; on free school accounts, up to 3 Audio Overviews a user a day.
- Best for: a revision recap where a paraphrase is the point.
- But: Google warns of inaccuracies, and you cannot fix one sentence.
ChatGPT or Claude, then a voice tool
- Script first: yes, as text you can check line by line.
- Voices: chosen in the second tool.
- Audio: from that tool.
- Price: free plans; paid from $8 a month for ChatGPT Go and $17 a month for Claude Pro, billed yearly.
- Best for: a careful script; Claude reads PDFs of up to 100 pages with their images and charts.
- But: two tools and a copy-paste.
ElevenLabs Studio and GenFM
- Script first: yes; Studio imports your text, and GenFM writes a conversation you can edit before it is voiced.
- Voices: a voice per paragraph; the Voice Library filters by accent.
- Audio: MP3 or WAV.
- Price: a free plan; GenFM needs a paid one.
- Best for: two-host audio with the script open to correction.
- But: the free plan has no commercial licence, and shared audio must credit ElevenLabs.
Articulate 360 AI (Storyline and Rise)
- Script first: yes; Storyline voices up to 10,000 characters you paste at a time, and Rise 360 drafts lessons from a document.
- Voices: named regional voices, such as Mia and Andrés for Spanish (Mexico).
- Audio: inside the course; Storyline also imports MP3 from any other tool.
- Price: $1,449 a seat a year.
- Best for: trainers who already build in Storyline or Rise.
- But: the price, and Storyline's narration starts from pasted text, not your PDF.
Kukarella
- Script first: yes, in the editor; change one paragraph and only that one is voiced again.
- Voices: 2,000+; the assistant casts from 22 by gender and age, so you pick the accent.
- Audio: MP3 or WAV, whole or by paragraph (by line in DialoguesAI); the script as TXT or DOC.
- Price: the assistant's script costs no credits, but Ask AI edits cost about 1 credit for every 5 characters; voicing is 1 credit a character with a ready-made voice; Prime is $21 a month for 300,000 credits.
- Best for: a narration or role-play in your learners' variety, made and fixed in one place.
- But: scripts can come back short, with no warning, and a scan is read only up to 20 pages, by an AI model that may skip an unclear word. No subtitles from Text to Voice or DialoguesAI; no promise about training; free-plan audio is for personal use only.
A human narrator, or your own voice
- Script first: yours, or an AI draft you check.
- Voices: exactly the one you need, if you can find the person.
- Audio: whatever you record.
- Price: time; ACX estimated in 2013 about four hours of work per finished audiobook hour.
- Best for: young children, feedback on one person's work, sensitive topics, a variety with few native AI voices.
- But: every change means recording again.
Can I use a textbook I didn't write, or a confidential policy?
You can voice your own material and text you hold a licence for. But a publisher's chapter belongs to the publisher, and a document you attach to the assistant is read by an AI model run by another company.
Rights. A voice licence covers the voice, not the words: only the publisher can license a publisher's chapter. In Kukarella, commercial rights come with a paid plan, and free-plan audio is for personal use only (more on commercial use).
Privacy, as it is. The text of a document you attach to the assistant goes to an AI language model run by another company, reached through OpenRouter. When you voice the script, its text also goes to the company that supplies the voice. Our Privacy Policy says our session recordings capture text you enter in the app, "such as scripts, prompts". Our Privacy Policy says nothing about training AI models. Our Terms of Use take a licence to what you upload "solely for the purposes of operating, providing, and improving the Service". Our home page FAQ says your files "stay while your account is open", that "We use them only to run and improve Kukarella", and that they are kept "On Google Cloud". We make no promise here about training. Google, for comparison, says data on its education accounts is not used to train AI models.
So take out learners' names first, and anything you would not email to a vendor: unpublished exams, staff records, health details.
How do my learners get the audio?
Download the audio as MP3, put it where your course already lives, and publish the script beside it as the transcript. But let the audio add to the document, not replace it.
Text to Voice downloads MP3 or WAV, as one file or one per paragraph, and the text as TXT or DOC. One file per paragraph suits a course: when a step changes, you replace one file.
Put the MP3 in your learning platform or shared drive, or link it from a QR code on the handout. For thinking time, place the cursor after a question and add a pause.
Subtitles. Text to Voice and DialoguesAI make none. TranscribeHub exports SRT: transcribe your finished MP3 there, using transcription minutes.
Accessibility. Under WCAG 2.2, success criterion 1.2.1, published audio-only content needs a text alternative that presents the same information, unless the audio only repeats text already on the page and is clearly labelled as such. A script rewritten for listening is new text, so publish it next to the audio. Audio helps the learner for whom the page is the obstacle.
 A dense textbook page can stop a student who struggles to read.
But keep the accessible document: audio adds to the text and does not replace it. The 46-study review ends on that point: learners need both audio and written options.
 Audio gives a student who struggles with print a second way into the lesson.
If you teach at a US public school, community college or public university, your institution falls under the federal web accessibility rule, now due by 26 April 2027 for public entities with a total population of 50,000 or more, and by 26 April 2028 for smaller ones and for special district governments. The rule is interim, so check the dates before you plan around them.
Three quick questions on what you would do with your own PDF:
Questions people ask
How do I make a presentation script from slides?
Save the deck as a PDF, because Kukarella's assistant does not take .pptx, and ask for a script slide by slide: a ten-minute talk over ten slides is about 150 words a slide.
Can AI just read my document aloud?
Yes. A read-aloud app reads it word for word, for your own listening. To give learners a file, use the "Media" icon in Text to Voice, choose a voice and download the MP3.
Can Kukarella read a photo of a textbook page?
Yes, saved as JPG or PNG, or as a scanned PDF. A scanned PDF is copied word for word, up to 20 pages; a photo of a page with a figure comes back summarised into its key points. The words still belong to the publisher.
How we checked
We read Kukarella's facts in our product code and live pages, and every outside source, on 3 October 2026, several studies in abstract only. Voice counts are from 1 October 2026; the length figures are single runs of our own, on 15 August, 2 October and 3 October 2026. The policy in the worked example is a sample we wrote; its runs, by both routes and as a scan, are dated 3 October 2026, the day Kukarella began reading scanned PDFs.
A correction: an earlier version of this page said our assistant runs text recognition on image-based PDFs (until 3 October 2026 it read only a PDF's text layer, and it now reads scanned pages with an AI vision model), that it is tuned to add drama, and that our privacy policy promises your data is never used for training; it also named two features our assistant does not have. We removed all of it, with unsourced statistics, a learning-styles claim (not justified by the evidence) and a brain-imaging study of nine people that never tested learning. Of the two older pages folded into this one, one showed characters from our demo videos as real teachers and the other quoted an unnamed teacher with no source; both are gone.