
Guidance, studies and Kukarella's limits checked on 28 October 2026.
A prompt is the instruction you give an AI model. For a script that people will hear, rather than read, a good prompt does five things: it names the listener and the purpose, gives the length in minutes, pastes a few lines of the voice you want, asks for writing for the ear (one idea per sentence, contractions, numbers written as words), and then asks the model to read its own draft as a listener and fix what trips. But a model writes plain and safe unless you show it otherwise, and a voice reads exactly what is on the page, so the last edit is yours. About 150 spoken words make a minute: a three-minute lesson narration is roughly 450 words.
We make one of the tools in this guide. Kukarella's assistant writes a narration or a dialogue for the ear by default and picks the voices, so you press Play in the same place. It writes in a neutral tone unless you ask for another, it cannot take a second pass at the same script, and its rules for the ear are instructions to the model, not checks. Each of those is covered below, with what to do about it in Kukarella or in ChatGPT, Claude or Gemini.
In this guide:
- What a prompt is, and what the people who build the models say makes a good one.
- Why an AI script sounds like AI.
- How to write the prompt for a script someone will hear, with a builder that writes it for you.
- The second pass, with a checker for your own script.
- One prompt, two scripts: hear the difference.
- Dialogues that sound like two people.
- Keeping a whole course consistent.
- What the voice does with what you wrote.
- Which AI should write it, and whether it will be flagged as AI.
What is a prompt, and what makes a good one?
Short answer: a prompt is everything you tell the model before it writes: the task, the reader, the limits and, best of all, an example. The companies that build the models agree on most of it. But the advice people skip is the one that works best: showing the model a sample instead of describing the style.
Anthropic, which makes Claude, asks you to treat the model as "a brilliant but new employee who lacks context on your norms and workflows", and offers a test: show the prompt to a colleague with little context on the task and see whether they could follow it (Anthropic, prompting best practices). Google's Gemini guide is blunter about examples: "We recommend to always include few-shot examples in your prompts" (Google, prompt design strategies, updated 13 October 2026). OpenAI suggests an order: who the assistant is, the instructions, the examples, then the material to work from (OpenAI, prompt engineering guide).
People who are not AI specialists tend to do the opposite. In a Berkeley study of ten such people designing a chatbot's prompt, "all participants held a strong bias for direct instruction over providing examples in-line". When they were shown that examples worked, "none subsequently made substantial use of examples" (Zamfirescu-Pereira and colleagues, CHI 2023). When participants pasted in lines from a chef's cooking video, their bot's whole manner shifted to match, down to the chef's habit of starting lines with "So, ...". Two participants said copying dialogue in felt like "cheating". It is not cheating. It is the most reliable way to set a voice.
What about starting with "Act as an expert…"? Two studies found that an expert role does not make answers more accurate (Zheng and colleagues, 2024; Wharton Generative AI Labs, December 2025). The Wharton authors still allow it one use, "altering the tone of outputs". For a script, that is the point: give a role to set the voice, not to make the facts right.
Why does an AI script sound like AI?
Short answer: because the model writes the most likely text, and the most likely text is smooth, general and slightly formal. Telling it to "sound human" gives it nothing to imitate. But part of the flatness is deliberate, in our tool as well: our assistant is told not to add drama you did not ask for.
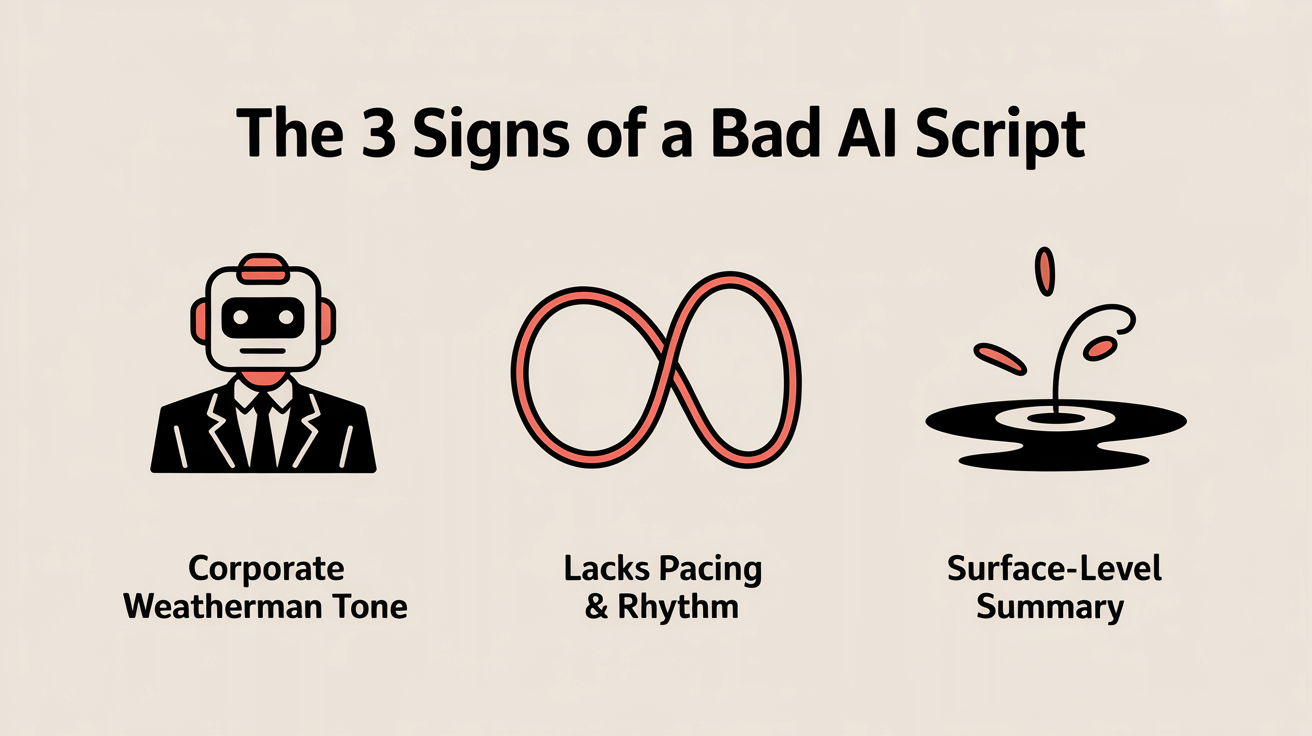 Three signs of a flat AI script: a stiff tone, no rhythm, and only a summary.
The habits are measurable. A team that analysed more than 15 million biomedical abstracts estimated that at least 13.5% of those published in 2024 had been processed with a language model, and found the word "delves" used 28 times more often than its earlier trend predicted. The extra words were "not content-related nouns, but rather style-affecting verbs and adjectives" (Kobak and colleagues, Science Advances, July 2025). Wikipedia's editors keep a field guide to the rest: "not just X, but also Y", lists of three, a promotional tone, and a vocabulary that changes with each model generation (Wikipedia: Signs of AI writing).
A listener notices different things from a reader. A long sentence with two clauses before the verb is fine on paper and lost in the ear, because a listener cannot go back. "Approximately 37.5%" is easy to read and awkward to hear. A list of five benefits in one breath leaves nobody remembering the third.
 Order a script and you get a can; direct it and you get a performance.
Kukarella's assistant is told, for both narrations and dialogues, to "write in a plain, neutral voice" and "not add drama… the user did not ask for" when the request names no tone, audience, purpose, length or level. We made it that way because a pronunciation drill or a safety briefing should not sound like a film trailer. The cost is that warmth, humour or tension only appear when your request asks for them.
How do I write the prompt for a script someone will hear?
Short answer: six parts, in this order: who is listening and why, how long, what to cover, a sample of the voice, the rules for the ear, and the words that must not change. The builder below writes it from your answers. But the sample matters more than every rule after it: if you only add one thing to your usual prompt, add that.
- Who is listening, and why. "Nurses in their first month, before a shift" is a listener. "An audience" is not. Say what they should be able to do afterwards.
- How long, in minutes and words. Most audiobook narrators read about 9,300 words an hour (ACX, Amazon's audiobook marketplace), so plan on 150 words a minute for a lesson: 450 words for three minutes, 750 for five. Models often come in short, so name the number.
- What to cover. The three points, the example, the term they must learn. Paste your notes or attach the document.
- A sample of the voice you want. Three to five sentences you have said to a class, or a paragraph from a script you liked. Anthropic calls examples "one of the most reliable ways to steer Claude's output format, tone, and structure", and suggests three to five.
- The rules for the ear. One thought per sentence and short sentences (UBC, Writing for the ear); contractions; numbers, dates and symbols written as you want them said ("forty-five dollars and sixty-seven cents", "Doctor", "one hundred percent", as ElevenLabs advises in its best practices for speech); no stage directions in brackets.
- Words that must not change. A safety warning, a policy line, a definition from the textbook. Ask for them exactly as given, contractions and all.
Say what you want instead of what you do not want. "Use everyday words a fifteen-year-old knows" works better than "Don't be too formal": Anthropic's guide says "Tell Claude what to do instead of what not to do", and in the Berkeley study a prompt saying "Do not say ABC" led the bot to say ABC.
A prompt built this way looks like this:
You are writing a script that a text-to-speech voice will read aloud. Nobody will see the text.

Listener: adult learners of English at level B1, in their second month of an evening course.
Purpose: after listening, they can ask for and give directions in a town centre.
Length: about 3 minutes, around 450 words.
Cover: turn left / turn right, go straight on, opposite, next to, the second street on the left.

The voice I want sounds like this (match its rhythm, not its topic):
"OK, so here's the thing. You're new in town. You've got your phone, but the battery's dead. What do you do? You ask someone. And that's what we're practising today."

Rules for the ear:
- One idea per sentence. No sentence over 16 words.
- Use contractions: you're, it's, don't.
- Write numbers and times as words, the way they should be said.
- No headings, lists, brackets or stage directions.

Keep this sentence exactly as written: "If you don't understand, it's fine to say: Sorry, could you say that again?"
The builder asks for the same six parts and gives you the prompt to copy, plus the second-pass prompt from the next section.
In Kukarella you paste the prompt into the assistant: "Use Assistant" in Text to Voice opens "What voiceover text can I create?" for one narrator, and in DialoguesAI it opens "What dialogue shall we write?" for two or more speakers. It writes the script and picks the voices; the audio is made when you press Play. Our assistant already asks the model for most of the rules in step 5 and for sentence lengths by level: for an A1 learner, five to eight words a sentence; for B1, twelve to sixteen. But they are instructions, not checks, so a sentence can still run long, and the length can come back short: in one of our own tests, a request for a two-minute dialogue came back at under a minute. Your own numbers in the prompt outrank its defaults.
 A lesson prompt with a voice sample, pasted into Kukarella's assistant.
What should the second pass ask?
Short answer: ask the model to read its draft as the listener would and rewrite whatever a listener would stumble on, then read it aloud yourself. But a model cannot hear its own script, and it will not catch a fact it invented, so the last pass is a person's.
Anthropic describes the loop as "generate a draft → have Claude review it against criteria → have Claude refine based on the review". For a script, the criteria are the listener's:
Read the script above as a listener who hears it once and cannot rewind.
List every sentence that is longer than 20 words, holds two ideas, starts with a long clause, or has a number, abbreviation or symbol that could be said two ways.
Then rewrite the script with those sentences fixed. Keep everything else, and keep the sentences I asked you to keep exactly as written.
Then do what writing-for-the-ear courses call the mouth edit: read it aloud at speaking pace. Where you run out of breath, the sentence is too long. Where you hesitate over how to say something, so will the voice: "read" can be present or past, "bass" a fish or a guitar, and "1/2" a date or a half. Rewording is simpler than any setting.
The check is not a formality. When The Washington Post launched personalised news podcasts written and voiced by AI in December 2025, people inside the paper flagged mispronunciations, invented quotes and quotes given to the wrong person in less than two days. The paper's head of standards called it "frustrating for all of us" (Semafor, 11 December 2025). A lesson has fewer readers than a newspaper, and each of them trusts the teacher more.
Paste your own script into the checker below. It marks long sentences, numbers worth checking, acronyms and abbreviations, brackets and symbols, and tells you how long the script will run at a lesson's pace.
One prompt, two scripts: hear the difference
Short answer: the same voice, the same topic, two requests. The first is one line; the second is the prompt from this guide. But the second is not perfect either, and what we would still fix is listed under it.
We made both in Kukarella's Text to Voice on 28 October 2026, with the voice the assistant picked the first time, Man With Deep Voice, and changed nothing by hand.
Request 1, one line: "Write a 3-minute lesson on asking for directions for B1 learners of English."
What came back: six paragraphs, 275 words, and 1 minute 34 seconds of audio, about half the length we asked for. It is correct and polite, and it reads like a handout: not one contraction ("If you do not understand, it is fine to ask again"), sentences of up to twenty-two words, and only the obvious direction words. "Opposite" and "the second street on the left" are not in it, because nobody asked for them. It opens:
Asking for directions is one of the most useful skills when you travel or study in a new place. If you are lost, stay calm, find someone nearby, and ask politely. A simple question can save you a lot of time.
A one-line request: 'Write a 3-minute lesson on asking for directions for B1 learners of English.'
Request 2, the prompt from this guide, with the voice sample and the rules for the ear, as shown above.
What came back: 447 words in 31 short paragraphs, and 2 minutes 44 seconds of audio. Every phrase on the list is in it, each with a line that says what it means; the sentence we asked to keep came back exactly as written; there are 21 contractions; and no sentence runs past 14 words. It sounds like someone talking to a class. It opens:
OK, so here's the thing. You're in a town centre, and you need to find a place. Maybe you want the bus station. Maybe you want a café. Maybe you're looking for the library. You ask someone for help. They answer. Now you need to understand the directions.
The full prompt from this guide, same voice.
But it is not finished. It took the sample's first line, "OK, so here's the thing", word for word, though we asked for its rhythm, not its topic; the builder in this guide now says "not its words". It overshot the length rule: told "no sentence over 16 words", it wrote most sentences under ten, and "You may hear" opens three of them in five lines. For B1 learners some sentences should be longer, which is why the builder asks for a range (twelve to sixteen words at B1) rather than a ceiling. And it still ran sixteen seconds short of three minutes. A teacher fixes those in a few minutes, and the second-pass prompt above finds most of them.
How do I make a dialogue sound like two people?
Short answer: ask for short turns, people who react to each other, and the small words of real talk: "Right.", "Sorry, which one?". But do not type hesitations: a voice reads "um" and "er" as words. And for learners, keep it tidier than real speech: real conversation at full speed is a different exercise.
Textbook dialogues are not how people talk. A comparison of textbook conversations with recordings of the same situations found that they "differ considerably" in length and turn-taking, false starts and repetition, pauses, overlap, hesitation and the listener's "mm-hm" (Gilmore, ELT Journal, 2004). An AI dialogue starts from the textbook end: every turn a full, correct sentence, every speaker waiting politely.
For a listening task, the usual compromise is in between: vocabulary at the learners' level, but short turns, one or two back-channels and contractions. Put that in the prompt in so many words, because "make it natural" gives the model nothing to do. Leave out written hesitations, though. In our own test, a native French voice read "Euh… je… bon" as word, pause, word, pause, not as someone hesitating.
For a staff training role-play the trap is different. Screenwriters call it "on the nose": "lines where characters say exactly what they think, feel, or intend without any subtext" (No Film School, 2024). An AI customer tends to announce "I am very frustrated", where a real one says "This is the third time I've called." Ask for the behaviour, not the label: "the customer interrupts once and repeats the order number."
A request for a dialogue adds three lines to the prompt above:
Speakers: two. Maria, a receptionist at a language school, and Tom, a new student who is a little late and lost.
Turns: mostly short. Tom interrupts once, and twice Maria says "Right" or "OK" before she answers. No "um" or "er".
Neither speaker says how they feel. Show it in what they say.
In Kukarella, a request in "What dialogue shall we write?" gives you the script with a voice for each speaker. Our assistant writes two speakers unless you say otherwise and is told that "Distinct does not mean opposed", so that it does not invent an argument you did not ask for. It also lets most turns run to more than one sentence, so ask for short turns if you want quick back-and-forth. It picks voices by gender and age, not by accent; for a particular accent, change the voice by hand. Our guides to listening dialogues and role-play dialogues for staff training go further.
How do I keep a whole course consistent?
Short answer: write one reference file for the course and give it to the AI with every request, outline the course before you script it, and script one lesson at a time with the outline and the lesson before it. But nothing remembers for you: in a new chat, or a new request, the file is the only memory there is.
A course is where AI scripts drift. Lesson one calls them "learners" and lesson six "students"; the narrator is warm in week one and formal in week four; a term defined in module two is defined differently in module five.
 One reference file for a whole course: audience, goals, glossary and teaching voice.
The reference file needs four things, on one page if possible:
- The listener: who they are, what they already know, their level.
- The goals: what each module should let them do.
- The glossary: the terms, defined once, in the words the course will use.
- The voice: the sample from the prompt above, and the words the course never uses.
Then work in order:
 Outline first, then each part with the outline and the part before it.
- Ask for the outline of the whole course, using the file. Correct it yourself; everything after depends on it.
- Ask for lesson one with the file and the outline.
- Ask for each next lesson with the file, the outline and the previous lesson's script, so it can pick up where the last one stopped.
- At the end, give the AI the scripts together and ask it to list contradictions: terms defined twice, numbers that disagree, a promise in lesson one that no later lesson keeps.
 Before you voice a long course, ask the AI to look for contradictions.
Keep each narration short. A review of studies on a conversational style in teaching found it helped learners apply what they learned (an effect size of 0.54) and remember it (0.30), but the effect faded in studies longer than about 35 minutes (Ginns, Martin and Marsh, 2013).
In Kukarella you can attach the reference file to each request: PDF, Word (.docx), plain text, or a JPG or PNG image, up to ten files of 20 MB each; not audio, video or a link. The file can set the subject, facts, tone and length, but not the language: the language comes from your request. Each request makes a new project and does not see the ones before it, so attach the file every time, and paste the previous lesson in if the next one should follow on.
What does the voice do with what you wrote?
Short answer: it reads it, all of it, as written. It does not follow stage directions and it does not tidy your numbers. But a few marks do change the delivery, and in Kukarella they are few and simple.
- Brackets and stage directions. "(warmly)" or "[pause]" are not instructions to a voice. Kukarella's assistant is told never to write them, and removes markers such as "[pause]" if one slips through. But words in round brackets stay in the text the voice receives, so delete them yourself, and check any script pasted from another chatbot.
- Pauses. In Kukarella, three full stops ("...") make a pause of about three-quarters of a second; a single "…" character does not. For a longer pause, place one at the cursor in the editor, from half a second to 90 seconds.
- Numbers, dates and abbreviations. Kukarella does not rewrite them before the voice reads them, so write them the way they should be said: "nine thirty", "twenty percent", "Doctor Patel".
- Emphasis and tone. Put them in the words. "That's the one thing to remember" carries emphasis a tag cannot. The voices our assistant chooses take no emphasis or pronunciation markup, and Amazon's neural and generative voices do not support an emphasis tag either (Amazon Polly, supported SSML tags): on modern voices, wording does the work.
- Speed. Set per speaker in the editor, from half to double speed. Not every voice has it.
A change after you have voiced a script, a word, a voice or a pause, is voiced again and charged again the next time you press Play, for the paragraph or line that holds it; unchanged lines are reused. The counter before Play shows the cost. Fix the text first, then voice it.
Which AI should write it: a chatbot or the voice tool's assistant?
Short answer: either works if the prompt is good. A general chatbot is better for back-and-forth; an assistant inside the voice tool saves the copying and already knows it is writing for the ear. But neither reads its script aloud before you do.
ChatGPT, Claude or Gemini
- Good at: a long conversation. You can ask for a shorter version, a warmer one, a version for a younger class, and it remembers the draft.
- Watch for: it writes for the page unless you give it the rules for the ear, and it may add headings, bullet points and stage directions that a voice cannot use.
- Cost: a free tier with limits, or a monthly plan; then you copy the text into a voice tool.
Kukarella's assistant
- Good at: a first script for the ear in one step, with the voices already picked, one for each speaker in a dialogue. Writing the script costs no credits; voicing it does.
- Watch for: one request, one script. It cannot revise its draft: "shorter" means a new request or your own edit. Neutral in tone unless you ask, and it picks voices by gender and age, not by accent.
- Cost: a limited number of requests on guest and free accounts, unlimited on paid plans.
Ask AI, inside a Kukarella project
- Good at: revising the script you already have, and it remembers the conversation.
- Watch for: it charges credits for each message, more as the conversation grows, and it does not apply the assistant's rules for the ear, so ask for them again.
Will the script be flagged as written by AI?
Short answer: no detector can tell you reliably. But that is a reason to say you used AI where your school or employer asks, not to hide it.
OpenAI withdrew its own AI-text classifier in July 2023 "due to its low rate of accuracy"; at launch it caught about a quarter of AI text and wrongly flagged about one human text in eleven (OpenAI, 2023). Stanford researchers found that detectors "consistently misclassify non-native English writing samples as AI-generated" (Liang and colleagues, Patterns, 2023), which matters to anyone teaching or training in a second language. Wikipedia's editors put it simply: "Humans are notoriously bad at distinguishing human and LLM-generated text." A script that sounds human because you gave it a listener, a voice and a second pass is a better script. Whether to disclose that AI drafted it is a question for your institution, not for a detector.
Questions teachers and trainers ask
How long should my prompt be?
As long as a colleague would need to do the job without asking you anything. The example in this guide is about 150 words. Most of the length is the sample and the words that must not change.
How many words for a five-minute narration?
About 750, at 150 words a minute. Ask for the number of words as well as the minutes, and check what comes back.
Should I start with "Act as a teacher"?
It sets the tone, not the accuracy. A sample of the voice you want does more than the role.
Can I put pauses or emotions in the script?
Not as instructions in brackets. In Kukarella, three full stops ("...") give a short pause, though a single "…" character does not, and the editor adds longer ones; emotion goes into the words.
What reading level should I ask for?
Name it: a CEFR level, a school year, or "a fifteen-year-old". Kukarella's assistant sets sentence lengths for CEFR levels and for JLPT, HSK and TOPIK, but the numbers you give outrank its defaults.
Can the assistant write from my slides or textbook page?
Yes, from a PDF, Word (.docx) or text file, or a JPG or PNG picture, that you attach. It takes the facts, tone and length from the file, but the language always comes from your request, and it cannot open a link.
How we checked
The advice from Anthropic, Google and OpenAI comes from their current guides, read on 28 October 2026. Every study is linked to the paper or its publisher's page. What Kukarella's assistant does, and what it is told, was read in the product's code on 28 October 2026 (production release a59acf17e). I made the recordings in Kukarella on 28 October 2026.